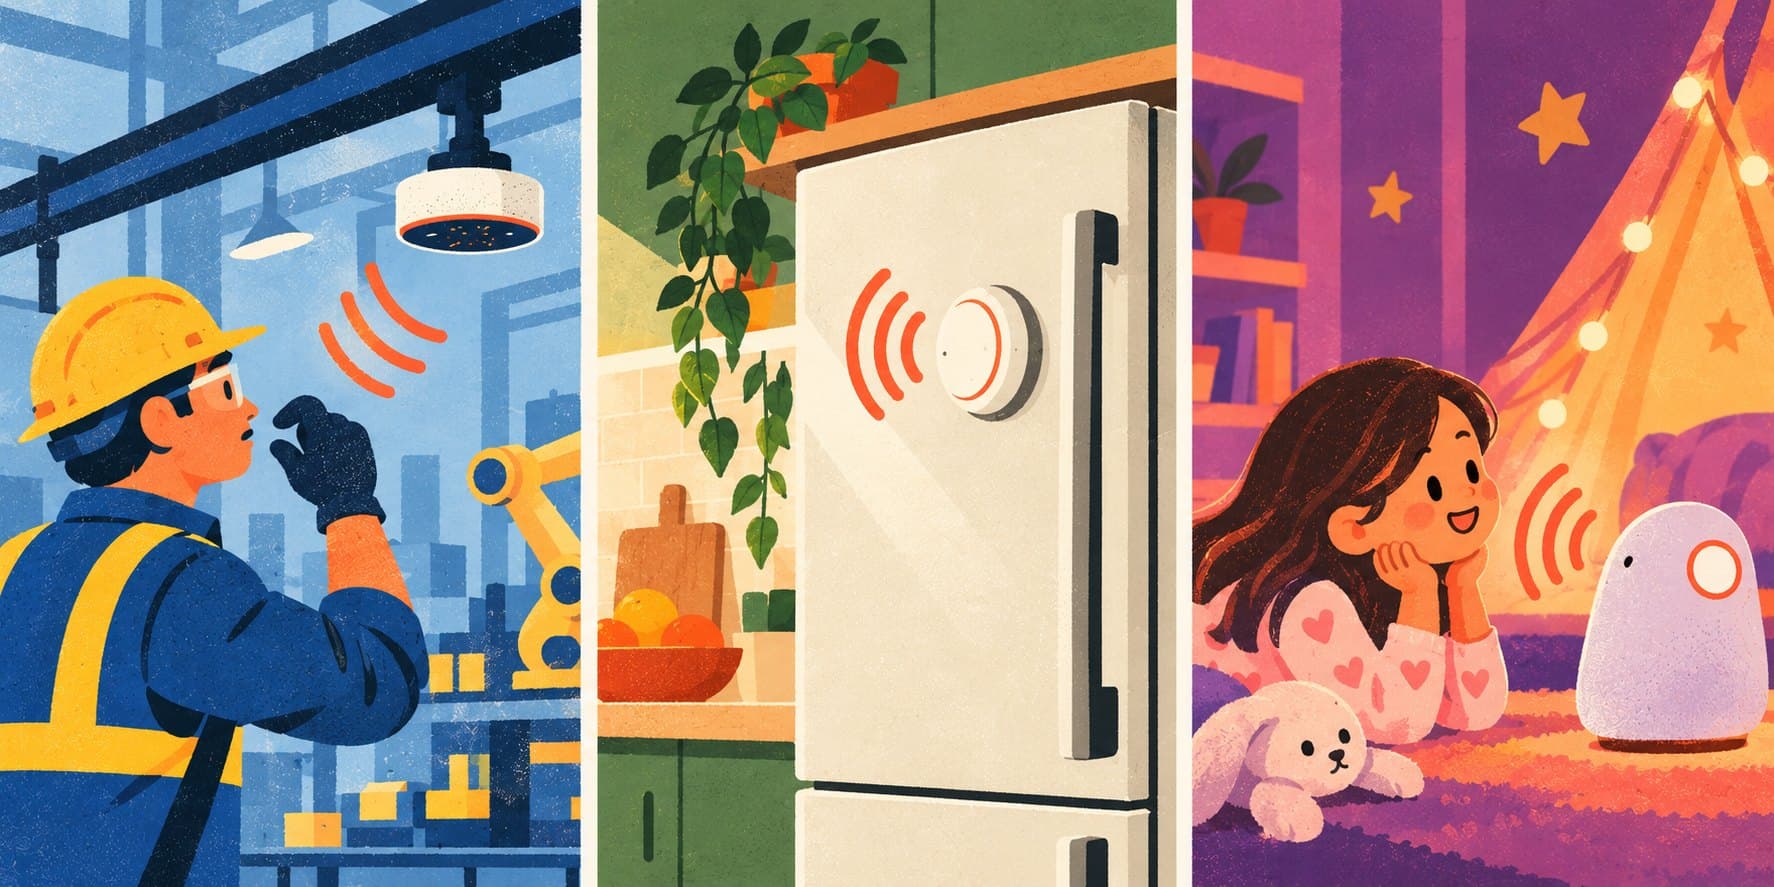
Build a low-cost conversational device with Higgs Realtime and Elato’s open-source stack. An ESP32-S3, a microphone and a speaker bring live, interruptible speech-to-speech interaction to low-power hardware.
Higgs Avatar can now join a LiveKit room and stream lip-synced video of your voice agent's speech while the agent is still talking. Same higgs-avatar model, same API key.
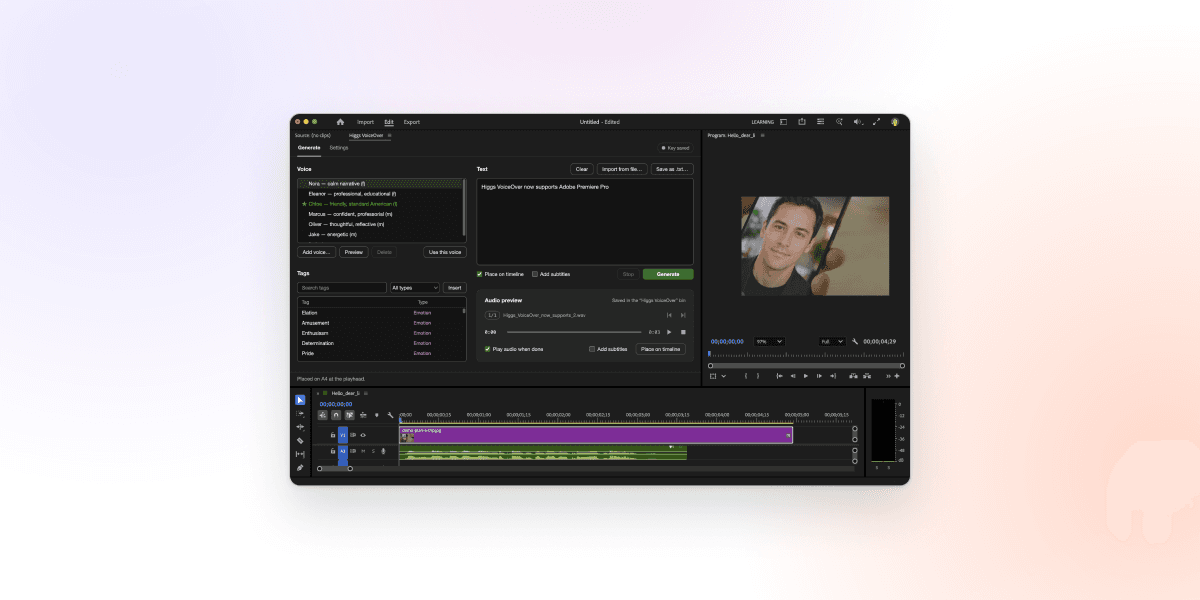
Higgs VoiceOver now works inside Adobe Premiere Pro, bringing directable AI voice-over, word-timed subtitles and custom voices to the Premiere timeline. Powered by Higgs TTS 3.
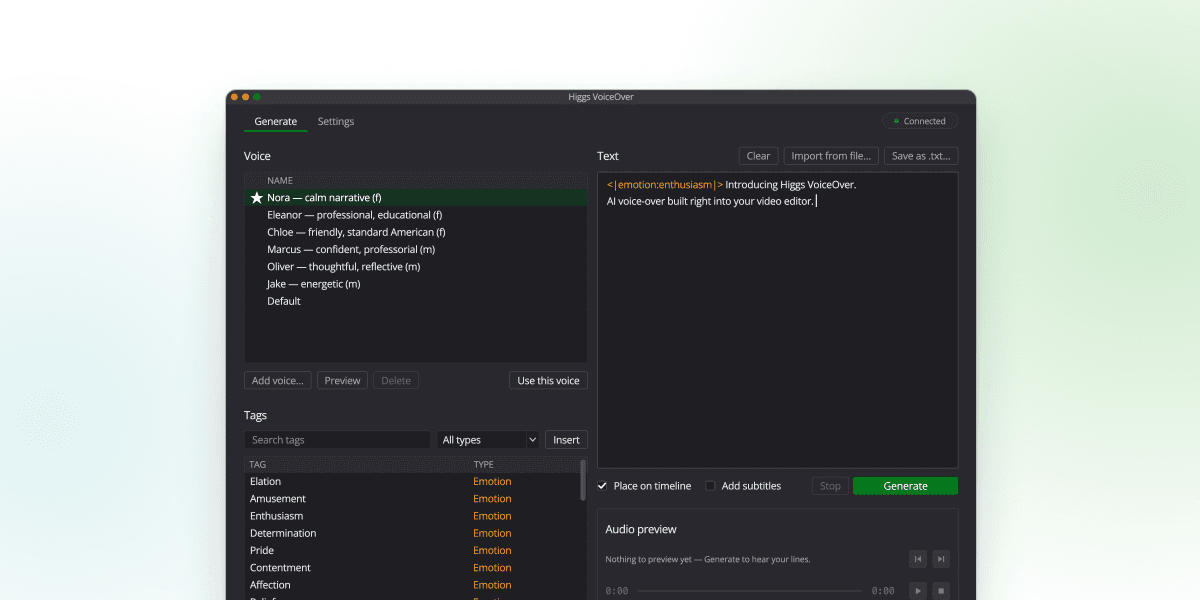
Higgs VoiceOver puts AI voice-over inside your video editor: direct each read for emotion, style and speed, generate word-timed subtitles, and build a custom voice from your own audio. Powered by Higgs TTS 3, available today for DaVinci Resolve Studio and Adobe Premiere Pro.
The Higgs TTS 3 API now rewrites input text the way a person would read it aloud, expanding numbers, dates, currency, URLs and abbreviations into spoken form. It can also return the start and end time of every word alongside the audio, so text can stay in step with speech.
pipecat-boson brings Higgs Realtime into Pipecat as a Realtime LLM service. One model takes live audio in and streams audio back, replacing the speech-to-text, language model, and text-to-speech chain — with interruption handling, function calling, 100+ languages, and audio out at $0.014 a minute.